Memory Ordering, Atomic Operations and Memory Barriers in Low-Latency Trading Systems | Trading Engineering — Deep Dive #10
Memory Ordering, Atomic Operations and Memory Barriers in Low-Latency Trading Systems
Trading Engineering — Deep Dive #10
Introduction
When we talk about performance in low-latency trading systems, we eventually arrive at a fundamental question:
How do multiple CPU cores exchange and observe data correctly while running concurrently?
In a simple program, we may imagine:
Thread A
   ↓
Memory Write
   ↓
Thread B
   ↓
Memory Read
Modern multicore CPUs, however, are much more complicated.
Each CPU core has its own cache hierarchy, and CPUs use mechanisms such as store buffers and out-of-order execution. Compilers may also reorder instructions as long as the observable behavior required by the language is preserved.
As a result, low-latency multithreaded systems must consider more than simply sharing variables.
Important concepts include:
- Atomic Operations
- Memory Ordering
- Memory Barriers
- Cache Coherency
- Acquire / Release
- Lock-Free Data Structures
- Ring Buffers
- False Sharing
This final Deep Dive examines how these concepts work together inside a latency-sensitive trading system.
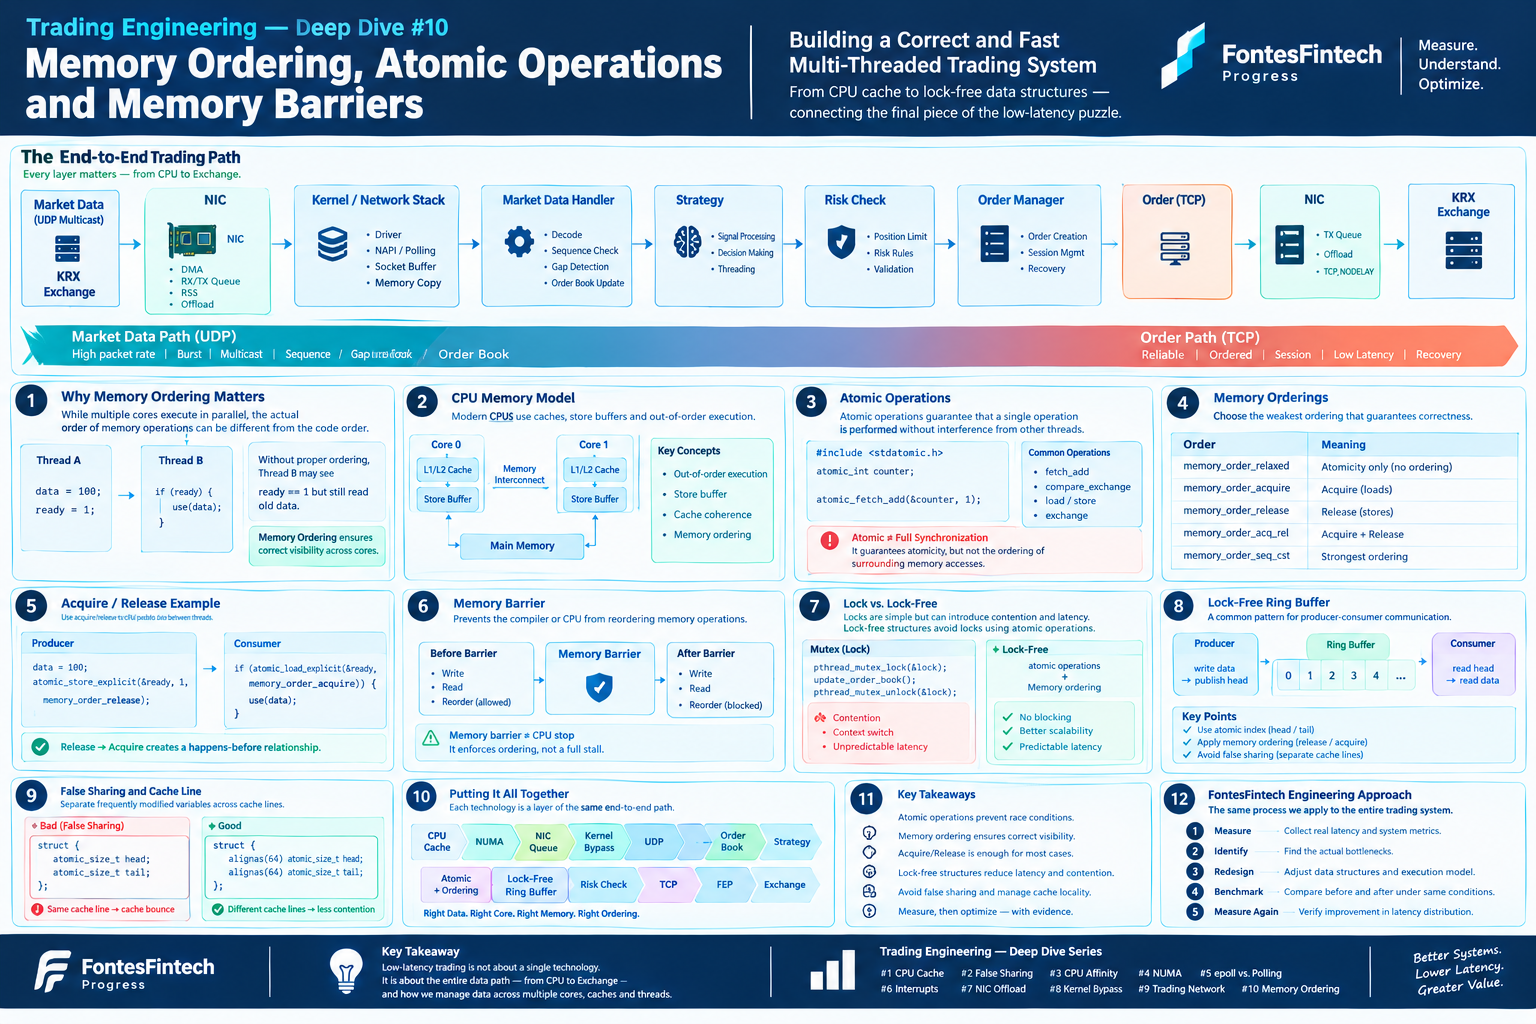
1. Memory Is Not Simple in a Multicore CPU
Modern CPUs execute multiple cores concurrently.
              CPU
       ┌───────┴───────┐
       │               │
     Core 0          Core 1
       │               │
     Cache            Cache
       │               │
       └───────┬───────┘
               │
             Memory
Suppose Thread A modifies some data and Thread B reads it.
Thread A                 Thread B

data = 100
   │
   └──────────────→     read data
Conceptually, this looks simple.
In reality, Cache Coherency, store buffers, compiler transformations, and memory-ordering rules can all affect how those operations are observed by another core.
Therefore:
The order written in source code should not automatically be assumed to be the order observed by another CPU core.
This is where memory ordering becomes important.
2. Why Can the Compiler and CPU Reorder Operations?
Consider:
data = 100;
ready = 1;
A developer naturally reads this as:
1. Update data
2. Set ready
Another thread might then do:
if (ready == 1) {
    use(data);
}
and expect data to contain 100.
However, concurrent programs cannot safely rely on this assumption without establishing the required synchronization relationship.
The compiler and CPU may perform transformations or execute memory operations in an order that differs from the apparent source-code order, while still satisfying the relevant language and hardware rules.
What we need is not merely an execution order.
We need a well-defined:
Memory ordering relationship between threads.
3. Atomic Operations
One of the fundamental tools for concurrent programming is the atomic operation.
Suppose multiple threads increment the same counter:
counter++;This operation is not inherently a single indivisible operation.
Conceptually, it may involve:
Thread A              Thread B

Read counter
                      Read counter
Add 1
                      Add 1
Write counter
                      Write counter
The result can therefore suffer from a race condition.
C11 provides atomic operations through <stdatomic.h>.
#include <stdatomic.h>

atomic_int counter;

atomic_fetch_add(&counter, 1);
An atomic operation provides the required atomicity for that operation according to the C memory model.
But there is an important distinction.
4. Atomic Does Not Mean Full Synchronization
This is one of the most important concepts in concurrent programming.
Atomicity and memory ordering are different properties.
For example:
data = 100;

atomic_store(&ready, 1);
and:
if (atomic_load(&ready)) {
    use(data);
}
The fact that ready is atomic does not, by itself, describe every ordering relationship between data and ready.
The important question is:
What synchronization relationship allows the consumer to safely observe the data published by the producer?
That is the role of memory ordering.
5. Memory Ordering
C11 atomics provide several memory-ordering options:
memory_order_relaxed
memory_order_acquire
memory_order_release
memory_order_acq_rel
memory_order_seq_cst
Each provides a different level of ordering guarantees.
Relaxed
Provides atomicity for the atomic object, but does not establish the stronger synchronization relationship provided by acquire/release.
Acquire
An acquire operation prevents relevant later memory operations from being reordered before the acquire, according to the C memory model.
Release
A release operation prevents relevant earlier memory operations from being reordered after the release and can publish preceding writes to an acquiring thread.
Acquire + Release
Provides both acquire and release semantics for a read-modify-write operation.
Sequentially Consistent
Provides the strongest commonly used ordering model among the standard C11 memory orders, imposing a single total order on sequentially consistent atomic operations.
The important point is:
Stronger ordering is not automatically better for a low-latency system.
The ordering should match the synchronization requirement.
6. Acquire / Release
Acquire and Release semantics are particularly important in producer-consumer designs.
Consider:
Producer
data = 100;

atomic_store_explicit(
    &ready,
    1,
    memory_order_release
);
Consumer
if (atomic_load_explicit(
        &ready,
        memory_order_acquire)) {

    use(data);
}
Conceptually:
Producer                     Consumer

data = 100
    │
    │
release store ───────────→ acquire load
                               │
                               ↓
                           use(data)
When the consumer observes the value through the corresponding acquire operation, the release/acquire relationship establishes the required ordering for the preceding data writes.
This pattern is fundamental to many lock-free queues and ring buffers.
7. Memory Barriers
A memory barrier, or memory fence, is a mechanism used to constrain the ordering of memory operations.
Conceptually:
Before Barrier
      │
      │
 ─────┼─────
      │
Memory Barrier
      │
 ─────┼─────
      │
After Barrier
A memory barrier does not simply mean:
"Stop the CPU."
Rather, it establishes ordering constraints between memory operations.
In modern C code, explicit atomic memory orders often provide a clearer way to express the required synchronization semantics.
The important principle is:
Use the synchronization primitive that expresses the actual ordering requirement.
8. Locks vs. Lock-Free Design
The most familiar way to synchronize threads is a lock.
pthread_mutex_lock(&lock);

update_order_book();

pthread_mutex_unlock(&lock);
Locks are extremely useful and often the right engineering choice.
However, in latency-sensitive systems, contention can become expensive.
Thread A
    ↓
Lock acquired
    ↓
Critical Section
    ↓
Lock released

Thread B
    ↓
Waiting
If many threads frequently access the same resource, lock contention can introduce:
- Waiting
- Context switching
- Scheduling variability
- Cache-line contention
- Tail-latency spikes
This is one reason lock-free data structures can be attractive in carefully designed low-latency systems.
9. What Does Lock-Free Really Mean?
A lock-free data structure avoids relying on traditional mutex locking for progress.
A common building block is:
Atomic Operations + Memory Ordering
A typical producer-consumer design is a ring buffer.
Producer
   │
   ▼
┌─────┬─────┬─────┬─────┬─────┐
│  0  │  1  │  2  │  3  │  4  │
└─────┴─────┴─────┴─────┴─────┘
                  ▲
                  │
               Consumer
The producer writes new data, while the consumer reads data that has already been published.
The difficult part is not simply the buffer itself.
The real challenge is:
How do we safely publish the producer's progress to the consumer?
This is where atomic indices and memory ordering become critical.
10. Memory Ordering in a Ring Buffer
Consider a simple SPSC — Single Producer, Single Consumer — ring buffer.
Producer                         Consumer

write data
    │
    ↓
buffer[index]
    │
    ↓
publish head ───────────────→ read head
                                  │
                                  ↓
                              read data
The producer must logically perform:
1. Write data
2. Publish the new head
The consumer must logically perform:
1. Observe the published head
2. Read the data
Conceptually:
Data Write
     ↓
Release
     ↓
Publish Index
     ↓
Acquire
     ↓
Read Data
Without the required ordering, the consumer could observe the publication before safely observing the associated data writes.
This is why memory ordering is not an academic detail.
It is part of the correctness of the data structure.
11. Why Ring Buffers Are Useful in Trading Systems
A simplified trading pipeline might look like:
Market Data Handler
        │
        ▼
   Ring Buffer
        │
        ▼
    Strategy
        │
        ▼
   Risk Engine
        │
        ▼
   Order Manager
Each processing stage can have a clearly defined responsibility.
In an SPSC design, we can often achieve:
- One producer
- One consumer
- Clear data ownership
- Simple index management
- Minimal locking
This can be particularly useful when moving high-frequency messages between well-defined processing stages.
It also connects directly to concepts discussed earlier in this series:
Cache Locality + False Sharing + CPU Affinity + Data Ownership
12. Atomic Indices Still Need Cache Awareness
Consider:
struct ring {
    atomic_size_t head;
    atomic_size_t tail;
};
Logically, this looks perfectly reasonable.
But if head and tail reside on the same cache line, the producer and consumer may repeatedly modify different variables while still invalidating the same cache line.
That can create cache-line bouncing.
In other words:
Using atomics does not automatically eliminate cache contention.
This is directly related to False Sharing, which we discussed in Deep Dive #2.
A low-latency ring buffer therefore needs to consider:
Atomic Operations
       +
Memory Ordering
       +
Cache Lines
       +
False Sharing
       +
Data Ownership
13. Data Ownership
One of the strongest design principles in low-latency systems is Data Ownership.
Instead of allowing multiple threads to continuously modify the same shared data:
Thread A
   │
   └── Owns Data A

Thread B
   │
   └── Owns Data B
we can explicitly define ownership.
When information needs to move between threads:
Thread A
   ↓
Message
   ↓
Ring Buffer
   ↓
Thread B
This reduces the amount of shared mutable state.
It can also reduce:
- Lock contention
- Cache-line bouncing
- False sharing
- Unnecessary synchronization
The principle is simple:
Prefer ownership and message passing over unrestricted shared state when the architecture allows it.
14. Applying This to a Trading System
A simplified trading system might look like:
             Market Data
                  │
                  ▼
          Market Data Handler
                  │
                  ▼
             Ring Buffer
                  │
                  ▼
              Strategy
                  │
                  ▼
             Risk Check
                  │
                  ▼
            Order Manager
                  │
                  ▼
                 FEP
                  │
                  ▼
              Exchange
Each stage can potentially have its own processing responsibility.
The objective is not to make every thread share every data structure.
Instead:
Each processing stage should own as much of its state as practical and pass only the information that the next stage actually needs.
This can make the system easier to reason about while reducing unnecessary synchronization.
15. Memory Ordering Is Both a Correctness and Performance Problem
Memory ordering is not merely a performance optimization.
Incorrect synchronization can produce incorrect data.
Consider:
Producer

Write Order
     ↓
Publish
and:
Consumer

Observe Publish
     ↓
Read Order
There must be a defined synchronization relationship between the publication and the data being published.
Without it, the consumer cannot simply assume that it will observe every related memory operation in the desired order.
Therefore, memory ordering addresses two things simultaneously:
Correctness
and
Performance
16. Is the Strongest Memory Order Always Better?
No.
Using the strongest possible memory ordering everywhere can introduce unnecessary synchronization constraints.
On the other hand, using an ordering that is too weak can break the correctness of the algorithm.
The goal is:
Use the weakest memory ordering that still guarantees correctness.
For example, a statistics counter may have very different requirements from a producer-consumer data publication mechanism.
A simple counter might use:
Atomic Counter
     ↓
Relaxed
while a publication protocol might require:
Data Write
    ↓
Release
    ↓
Publish Index
    ↓
Acquire
    ↓
Data Read
This distinction is especially important when optimizing highly active code paths.
17. Lock-Free Does Not Always Mean Faster
Another important lesson is:
Lock-Free ≠ Always Faster
Lock-free designs can still incur costs such as:
- Atomic operations
- Cache coherency traffic
- Memory-ordering constraints
- CAS retries
- Cache-line contention
- Busy waiting
- More complicated recovery logic
For example, if many CPUs repeatedly update the same atomic variable, the corresponding cache line can bounce between cores.
In some workloads, a carefully designed lock may actually perform better.
Therefore, removing a mutex is not itself a performance optimization.
18. Connecting the Entire Deep Dive Series
At this point, the entire Deep Dive series can be connected into a single system.
CPU Cache
    ↓
False Sharing
    ↓
CPU Affinity
    ↓
NUMA
    ↓
Polling
    ↓
Interrupt / NAPI
    ↓
NIC / RX Queue
    ↓
Kernel Networking
    ↓
Kernel Bypass
    ↓
UDP Market Data
    ↓
Order Book
    ↓
Strategy
    ↓
Atomic / Memory Ordering
    ↓
Lock-Free Ring Buffer
    ↓
Risk Check
    ↓
TCP Order Flow
    ↓
FEP
    ↓
Exchange
These may initially look like separate technologies.
They are not.
They are different layers of the same end-to-end system.
The underlying question is always:
How can information move through the system with minimum latency and predictable behavior?
19. The FontesFintech Engineering Approach
In low-latency systems, the goal is not to use a particular technology simply because it is considered "high performance."
The goal is to understand the complete data path.
We start with one question:
Where is the latency actually being spent?
Then we follow an engineering cycle.
Measure
Measure latency and system behavior.
Identify
Identify the actual bottleneck.
Redesign
Change the architecture or implementation where necessary.
Benchmark
Compare the new design against the original under equivalent conditions.
Measure Again
Verify that the latency distribution has actually improved.
This approach treats:
CPU → Cache → Memory → Network → NIC → Kernel → Application
as one connected system rather than a collection of independent components.
The ultimate objective is not simply lower average latency.
It is:
Correctness → Performance → Predictability
Conclusion
At the deepest level of a low-latency trading system, we eventually reach the CPU memory model itself.
Cache
→ Memory
→ Atomic Operations
→ Memory Ordering
→ Lock-Free Design
→ Data Ownership
All of these concepts ultimately serve one purpose:
Move information quickly and predictably between multiple CPU cores without sacrificing correctness.
A low-latency system is not simply about using a faster CPU.
We need to understand:
Which Core executes the thread
Which Memory the data resides in
How data is shared
In what order memory operations become visible
How information moves between processing stages
This leads to the final principle of the series:
Right Data. Right Core. Right Memory. Right Ordering.
And, as always:
Measure First. Optimize with Evidence.
Trading Engineering — Deep Dive Series Complete
#1 — CPU Cache
#2 — False Sharing
#3 — CPU Affinity & Core Pinning
#4 — NUMA & Memory Locality
#5 — epoll vs. Busy Polling
#6 — Interrupts, Polling & Network Latency
#7 — NIC Offload & Kernel Networking
#8 — Kernel Bypass & User-Space Networking
#9 — UDP Market Data & TCP Order Flow
#10 — Memory Ordering, Atomic Operations & Lock-Free Design
From CPU → Memory → Thread → Network → NIC → Kernel → Trading Application → Exchange.
That is the complete path of a low-latency trading system.
Measure the Path. Understand the Bottleneck. Optimize with Evidence.
FontesFintech — Progress
"
Throughout this series, I would give ChatGPT a topic, review its response, make corrections, and go through the process again — exchanging ideas and feedback along the way.
Even the process itself has been fascinating to experience.
As we step into the incredible era of AI that lies ahead, I hope we can all adapt, learn to work alongside AI, and create a more harmonious way of living together.
"